Reddit Scraper | Posts | Comments | Subreddit Data
Merci · @mercidev
Scrape Reddit posts, comments, user profiles and subreddits by URL or keyword - full text, scores, authors and timestamps for sentiment, trend and research.
About
Reddit Scraper Pro - Posts, Comments, Users and Subreddit Data
The Reddit Scraper Pro collects public Reddit posts, comments and user profiles by URL or keyword. It returns full post text, scores, authors, timestamps, subreddit, flair, media links, comment text and basic user karma without requiring a Reddit API key.
Use it for sentiment research, trend detection, community monitoring, product feedback and audience analysis. The Actor uses an RSS-first strategy, then falls back to embedded JSON and modern Reddit HTML parsing when available. One dataset row represents one post, comment or user record.
Main Use Cases for Reddit Community Research
- Sentiment analysis - collect post and comment text for brand, product or market sentiment research.
- Trend detection - monitor keywords and subreddits for emerging topics and recurring questions.
- Community monitoring - track new posts, scores and comment activity in a niche subreddit.
- Product feedback - gather candid user complaints, feature requests and comparisons.
- Competitor research - analyze how users discuss competing products and brands.
- Audience discovery - identify active users and subreddits for a topic.
- AI research pipelines - feed an LLM source-linked posts and comments with timestamps.
How It Works
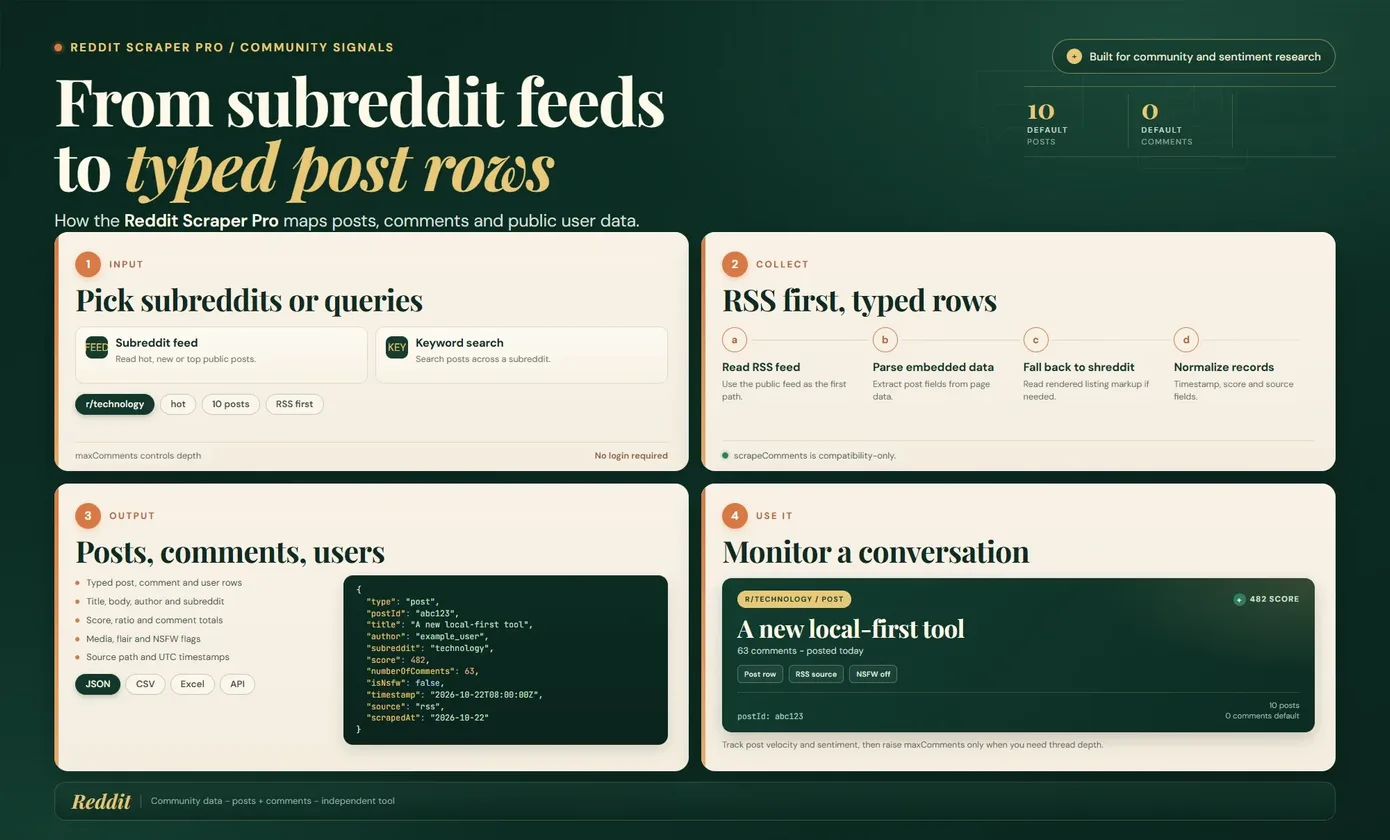
Provide subreddit, post or user URLs in startUrls, or use searchKeywords to run Reddit searches. The Actor classifies each URL before fetching: subreddit pages are paginated, post URLs are parsed for a post plus comments, and user URLs are fetched only when scrapeUsers is enabled.
The parser tries multiple public surfaces. It first reads RSS where possible, then embedded JSON and modern shreddit HTML, with a legacy article fallback. This design keeps the Actor working when one Reddit surface is blocked or returns a JavaScript shell, but the exact fields can differ by source strategy.
Post rows carry title, body, author, score, upvote ratio, comment count, subreddit, flair, NSFW and spoiler flags, timestamps, media URLs and a source marker. Comment rows carry comment ID, post ID, author, comment text, score, permalink, subreddit and timestamp. User rows carry username, total karma and profile URL.
maxPosts is shared across all subreddit, post and search sources. maxComments is the effective comment budget, and the current build uses it as the reliable comment control; scrapeComments is present for compatibility. Set maxComments to zero to skip comment extraction. A deleted or renamed post can return a post row with zero comments even when a larger budget was requested.
Input
Use URLs, search keywords or both. The post and comment budgets are shared across the whole run, so a large URL list does not multiply the limits.
| Field | Type | Required | Default | What it does |
|---|---|---|---|---|
startUrls | string[] | Yes | r/programming | Subreddit, post or user profile URLs. User URLs are processed only when scrapeUsers is enabled. |
searchKeywords | string[] | No | [] | Keywords searched on Reddit. Each keyword can produce its own result set within the post budget. |
maxPosts | integer | No | 10 | Maximum posts saved across all sources. |
maxComments | integer | No | 0 | Maximum comments saved across all post URLs. Zero skips comments. |
sortBy | string | No | new | Sort order for subreddit or search results, such as new, hot, top or relevance. |
scrapePosts | boolean | No | true | Whether to save post records. |
scrapeComments | boolean | No | false | Present for compatibility. Use maxComments as the effective comment budget in the current build. |
scrapeUsers | boolean | No | false | Whether to process user profile URLs and save basic user records. |
proxyConfiguration | object | No | None | proxy configuration. Use a proxy for larger or repeated runs. |
Start with one subreddit URL and a small post budget. Add post URLs and raise maxComments only after confirming which parser path Reddit serves. Reddit changes its HTML and rate limits frequently, so a run that returns RSS-level fields may omit comment-level detail. Empty comments are not necessarily a parser failure; the post may be deleted, locked or RSS-only.
Output
Rows have a type of post, comment or user. The field set varies by type and by the parsing surface that succeeded.
| Field group | Fields | What you get |
|---|---|---|
| Record type | type, _source | Whether the row is a post, comment or user, plus the parser strategy that produced it. |
| Post | postId, title, postText, url, text, author, subreddit, flair | Post identity, body, permalink, author, subreddit and flair. |
| Engagement | score, upvotes, downvotes, upvoteRatio, numberOfComments | Net score, vote counts, ratio and comment count when the surface exposes them. |
| Comment | commentId, commentText, permalink, score, username | Comment identity, body, permalink, score and author. |
| User | username, totalKarma, profileUrl | Basic public profile record when a user URL is processed. |
| Media and flags | externalUrl, mediaUrls, isNsfw, isSpoiler, isStickied | Outbound link, media URLs and post flags. |
| Time | timestamp, createdAt, createdUtc | ISO timestamp, RSS creation text and Unix creation time when available. |
| Search provenance | searchKeyword | The keyword that produced a search row. |
RSS post rows can have comments: 0 and no numberOfComments, while HTML rows may expose a richer field set. upvoteRatio is often null. A user record contains only basic karma and profile data, not a full posting history. Check _source before comparing rows, because field availability is parser-dependent.
Example Input
{
  "startUrls": [
    {
      "url": "https://www.reddit.com/r/programming/"
    }
  ],
  "maxPosts": 25,
  "maxComments": 100,
  "sortBy": "new",
  "scrapeComments": true,
  "scrapeUsers": false,
  "proxyConfiguration": {
    "useProxy": true
  }
}
This fetches up to 25 new posts from r/programming and up to 100 comments from any post URLs. A subreddit-only URL produces posts; to test comments, add a specific post URL.
Example Output
{
  "type": "post",
  "postId": "1xci6t4",
  "title": "System Design Masterclass: 8 Patterns Behind High-Scale Distributed Systems",
  "url": "https://www.reddit.com/r/programming/comments/1xci6t4/system_design_masterclass_8_patterns_behind/",
  "text": null,
  "author": "u/mostaptname",
  "comments": 0,
  "createdAt": "2026-10-22T13:11:49+00:00",
  "subreddit": "r/programming",
  "score": 0,
  "_source": "rss"
}
This is a real RSS-backed post row. The text and createdAt shapes differ from HTML rows, and comments is an RSS count field rather than the number of scraped comments. Check _source when normalizing.
Integrations and Automation
Call the Actor through the API, MCP, a schedule, Zapier, Make or n8n. Export JSON, CSV or Excel, or push rows to Google Sheets, Airtable, a database, a sentiment model or a webhook.
For sentiment, separate posts and comments with type, clean text, and keep score and createdAt so a model can weight recency and engagement. Do not treat an RSS row with zero comments as proof that a discussion had no replies.
For monitoring, deduplicate on postId or commentId and store _source and the scrape timestamp. Schedule runs at a cadence that respects Reddit rate limits, and keep a proxy enabled for larger jobs.
FAQ
Do I need a Reddit API key?
No. The Actor uses public RSS, HTML and embedded data surfaces and does not require a Reddit developer account or OAuth token.
Why did a post have no comments?
The post may be deleted, locked, RSS-only or served from a surface without comment HTML. Raise maxComments and use a direct post URL, but expect some posts to remain empty.
Is scrapeComments applied?
The field is present for compatibility. In the current build, use maxComments as the effective comment budget and set it to zero to skip comments.
How many users can I collect?
User records are produced only for user profile URLs when scrapeUsers is true. Each user row contains basic karma and profile data, not a full posting history.
Are post and comment fields consistent?
Not always. RSS, embedded JSON and HTML rows can expose different fields. Check _source before comparing comments, createdAt or vote fields.
Is maxPosts shared across URLs and keywords?
Yes. The post budget is global for the run, not per subreddit or keyword. The same applies to maxComments across post URLs.
For AI Agents and LLM Apps
The Actor provides source-linked Reddit posts, comments and basic user records with scores, timestamps and parser provenance. It is suitable for sentiment, trend and community-research agents through the API or MCP.
- Branch on
typebefore reading fields; post, comment and user rows are different shapes. - Read
_sourceto understand field availability, especially for comment counts and RSS timestamps. - Do not treat a zero comment count as proof of no discussion; the surface may not expose comments.
- Deduplicate on
postIdorcommentIdand keepcreatedAtortimestampfor recency weighting. - The post and comment budgets are global for the run, and every saved row is billable.
Legal and Compliance
This Actor is an independent tool and is not affiliated with, endorsed by or sponsored by Reddit. It reads publicly available posts, comments and profiles for research and monitoring. Reddit terms, subreddit rules and applicable privacy law still apply.
Reddit content can include personal data and copyrighted text. Use it for legitimate research, keep only what you need, honor deletion requests and do not republish content in violation of copyright or privacy rights. Avoid using the Actor for harassment, surveillance or manipulation.
SEO Keywords
Reddit scraper, Reddit posts scraper, Reddit comments scraper, Reddit API alternative, Reddit user data, subreddit scraper, Reddit sentiment analysis, Reddit market research, Reddit dataset, Reddit keyword search, Reddit monitoring, Reddit comments dataset, Reddit research tool, Reddit post data, community sentiment data, Reddit trend detection, Reddit profile scraper, social media research, Reddit lead generation, Reddit JSON alternative
FAQ
- Do I need a Reddit API key?
- No. The Actor uses public RSS, HTML and embedded data surfaces and does not require a Reddit developer account or OAuth token.
- Why did a post have no comments?
- The post may be deleted, locked, RSS-only or served from a surface without comment HTML. Raise maxComments and use a direct post URL, but expect some posts to remain empty.
- Is scrapeComments applied?
- The field is present for compatibility. In the current build, use maxComments as the effective comment budget and set it to zero to skip comments.
- How many users can I collect?
- User records are produced only for user profile URLs when scrapeUsers is true. Each user row contains basic karma and profile data, not a full posting history.
Input
Preview of the input form. Rent the Actor to fill it in and start runs from the console.
Fields
startUrlsList of Reddit URLs to scrape. Supports subreddit, post, and user profile URLs.
searchKeywordsKeywords to search on Reddit. Each keyword triggers a separate search.
maxPostsMaximum number of posts to scrape across all sources.
maxCommentsMaximum number of comments to scrape across all sources.
sortByHow to sort subreddit posts or search results.
scrapePostsWhether to scrape post data.
scrapeCommentsWhether to scrape comments from posts.
scrapeUsersWhether to scrape user profile data.
Use Apify proxy or custom proxies to avoid rate limiting.
proxyConfigurationApify proxy configuration.
API
Bytewells speaks the Apify API. Existing integrations keep working: point apify-client at https://bytewells.com/api and use your Bytewells API token (Console → Settings → API access). The Actor ID is mercidev/reddit-scraper-pro (or mercidev~reddit-scraper-pro in URLs).
JavaScript · apify-client
import { ApifyClient } from 'apify-client';

const client = new ApifyClient({
  token: process.env.BYTEWELLS_TOKEN,
  baseUrl: 'https://bytewells.com/api',
});

const input = {
  "startUrls": [
    {
      "url": "https://www.reddit.com/r/programming/"
    }
  ],
  "searchKeywords": [],
  "maxPosts": 10,
  "maxComments": 0,
  "sortBy": "new",
  "scrapePosts": true,
  "scrapeComments": false,
  "scrapeUsers": false
};

const run = await client.actor('mercidev/reddit-scraper-pro').call(input);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);
Python · apify-client
import os
from apify_client import ApifyClient

client = ApifyClient(os.environ["BYTEWELLS_TOKEN"], api_url="https://bytewells.com/api")

run_input = {
    "startUrls": [
        {
            "url": "https://www.reddit.com/r/programming/"
        }
    ],
    "searchKeywords": [],
    "maxPosts": 10,
    "maxComments": 0,
    "sortBy": "new",
    "scrapePosts": True,
    "scrapeComments": False,
    "scrapeUsers": False
}

run = client.actor("mercidev/reddit-scraper-pro").call(run_input=run_input)
items = client.dataset(run["defaultDatasetId"]).list_items().items
print(items)
HTTP · curl
curl -X POST "https://bytewells.com/api/v2/acts/mercidev~reddit-scraper-pro/runs" \
  -H "Authorization: Bearer $BYTEWELLS_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"startUrls":[{"url":"https://www.reddit.com/r/programming/"}],"searchKeywords":[],"maxPosts":10,"maxComments":0,"sortBy":"new","scrapePosts":true,"scrapeComments":false,"scrapeUsers":false}'
Runs are billed as compute from your credit balance. Paid Actors need an active rental or trial; otherwise the API answers 402 rental-required.
Related
More Actors from the same publisher.
Pinterest Scraper | Pins | Search | Comments | Leads
Merci · @mercidev
The cheapest Pinterest scraper. Extract pins, search results, boards, and profiles with engagement stats, follower counts, comments, and HD image URLs.
MarketingSEO toolsSocial media$19/mo1-day free trial
SoundCloud Scraper | Track Data & Direct Stream Links
Merci · @mercidev
Extract track and artist data from SoundCloud — titles, play counts, genres, stream links and engagement metrics for music analytics and discovery.
AIE-commerceLead generation$29/mo1-day free trial
X (Twitter) Quotes & Reposts Scraper
Merci · @mercidev
Collect every quote tweet and every account that reposted any X post, over plain HTTP against X's own GraphQL endpoints.
AutomationE-commerceLead generation$15/mo1-day free trial
Mobile.de Scraper | German Car Listings
Merci · @mercidev
Collect mobile.de vehicle listings across Germany. Get prices, mileage, first registration, power, fuel, gearbox, body type and other fields.
AIAutomationDeveloper tools$20/mo1-day free trial