X (Twitter) Quotes & Reposts Scraper
Merci · @mercidev
Collect every quote tweet and every account that reposted any X post, over plain HTTP against X's own GraphQL endpoints.
About
X (Twitter) Quotes & Reposts Scraper — Retweeter & Quote-Tweet Data
For any X post, collect every quote tweet (with author profile, engagement counts, text and media) and every account that reposted it (handle, display name, bio, avatar, follower counts). Runs over plain HTTP against X's GraphQL endpoints — no browser, no proxy.
Main Use Cases
- Engagement & amplification analysis — see exactly who quoted and who reposted a post, with follower counts and verification status.
- Influencer & lead discovery — turn a viral post into a list of engaged accounts with bios and profile URLs.
- PR / crisis monitoring — capture quote tweets (with full text) as they appear around a launch or announcement.
- Competitive intelligence — measure how far a competitor's post actually spread, beyond the vanity counter.
- Sentiment research — export quote-tweet text and author data for NLP on how a post was received.
How It Works
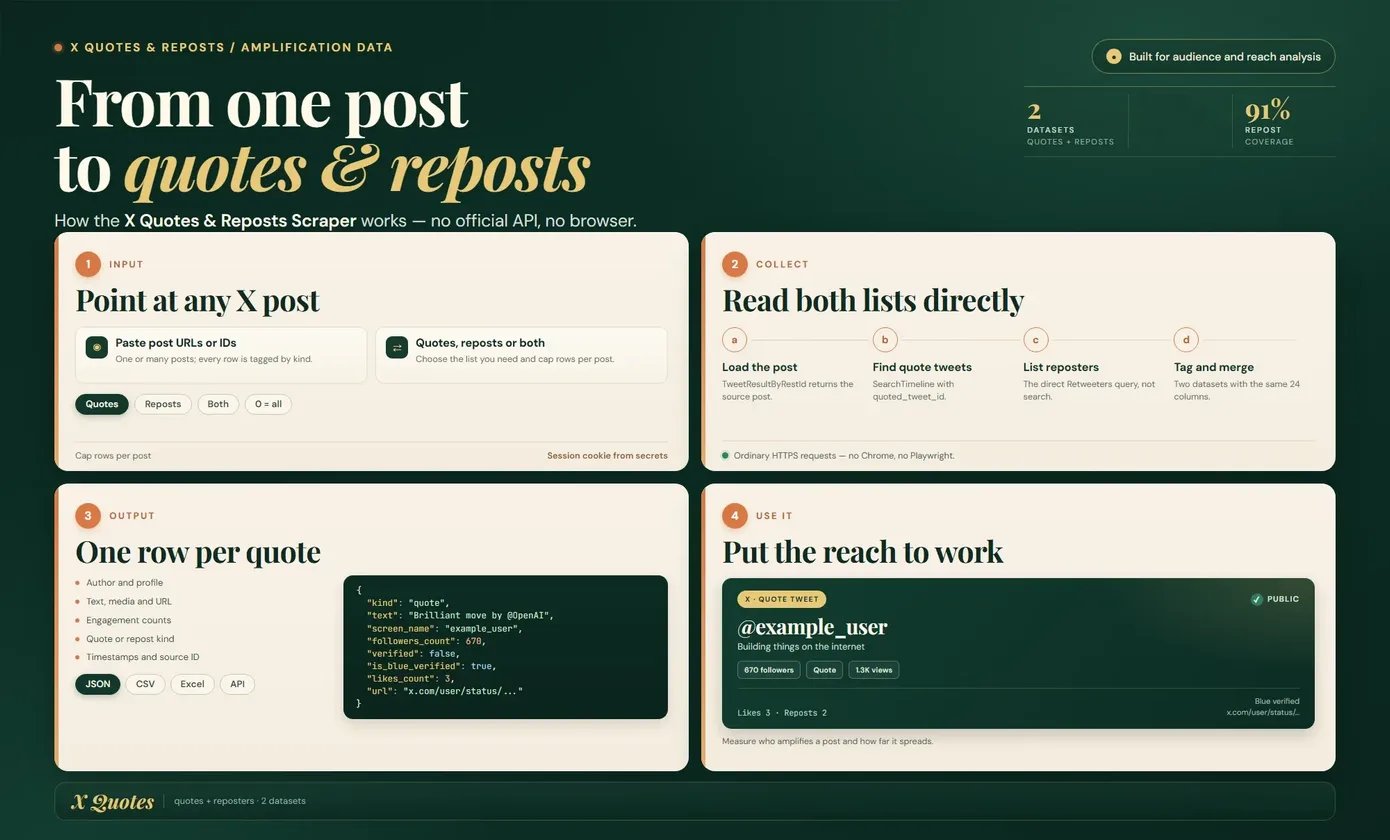
Both lists are login-only on X, so a session cookie is required — the actor reads it from secrets (X_AUTH_TOKEN / X_CT0), so it never appears in the input or run record. It mints X's public x-client-transaction-id header from the app shell (deterministic, not a secret), then calls TweetResultByRestId for the source post, SearchTimeline with quoted_tweet_id:<id> for quote tweets, and Retweeters for the accounts that reposted. Everything is ordinary HTTPS requests — no Chrome, no Playwright.
Give it one or more post URLs or IDs, choose quotes, reposts or both, and the actor returns structured rows with author profiles, engagement counts and source timestamps.
Collect Quote Tweets And Reposts Without The Official X API
X's official API does not expose the account list for reposts, and gates quote tweets behind expensive tiers. This actor returns both as structured JSON with author profiles and engagement counts, and does it over plain HTTP.
Input
| Field | Type | Required | Default | Notes |
|---|---|---|---|---|
tweetUrls | array | yes | — | X post URLs (https://x.com/user/status/123…) or bare numeric post IDs. Multiple posts are fine. |
collect | select | no | quotes | quotes, reposts or both. Every row is tagged kind. |
maxQuotesPerPost | integer | no | 0 | Quote tweets per post. 0 = keep going until X stops serving new ones. |
maxRepostsPerPost | integer | no | 0 | Reposting accounts per post. 0 = keep going until X stops serving new ones. |
There is no proxy field — the actor makes ordinary HTTPS requests and does not need one. There is no cookie field either; the session is read from secrets. You state rows, and the actor derives pagination depth from that.
Output
Rows are split across two datasets, each with its own schema; both expose the same 24 columns so a merged export still parses (kind tells them apart). Views: overview and all.
collect | default dataset | reposts dataset |
|---|---|---|
quotes | quote rows | (not created) |
reposts | (empty) | repost rows |
both | quote rows | repost rows |
Both datasets share these fields: source_tweet_id, kind, quote_tweet_id, quoted_tweet_id, url, created_at, text, screen_name, user_id, user_name, avatar_url, bio, followers_count, following_count, verified, is_blue_verified, replies_count, retweets_count, likes_count, views_count, media_count, media_urls, source, collected_at.
Notes: for repost rows the post-specific columns (created_at, text, engagement counts) are null — a native repost has no post of its own — and url points at the retweeter's profile. A run summary (collected counts vs X's reported counts, coverage %, stop condition, billed events, errors) is stored as the key-value store item OUTPUT.
Coverage
Coverage is not 100%, and the reason is on X's side: X hides quote tweets and reposts from deleted, suspended and protected accounts. The /quotes tab is backed by X's search index, which only exposes a slice of very large threads (a post reporting 1,582 quotes typically yields a few hundred rows, ~15–40%). The repost list is a direct query, not routed through search, so it lands much closer to the reported count — the reference run collected 1,584 of 1,744 reposts (~91%), ending on X's own last page rather than on a cap. OUTPUT.coverage_pct and OUTPUT.reposts_coverage_pct always report the real ratio; both go to null when a configured limit or a spending limit ended the list, and stopped_by / reposts_stopped_by say which case occurred.
Example Input
{ "tweetUrls": ["https://x.com/OpenAI/status/2065225362544726371"], "collect": "both" }
Quote tweets only, capped:
{ "tweetUrls": ["2065225362544726371"], "collect": "quotes", "maxQuotesPerPost": 200 }
Example Output
kind: "quote" (default dataset):
{
  "source_tweet_id": "2065225362544726371",
  "kind": "quote",
  "quote_tweet_id": "2065231677539176538",
  "quoted_tweet_id": "2065225362544726371",
  "url": "https://x.com/user/status/2065231677539176538",
  "created_at": "Fri Jun 12 00:36:16 +0000 2026",
  "text": "Brilliant move by @OpenAI",
  "screen_name": "example_user",
  "user_id": "1416365362505863169",
  "user_name": "Example User",
  "bio": "Building things on the internet.",
  "followers_count": 670,
  "following_count": 2206,
  "verified": false,
  "is_blue_verified": true,
  "replies_count": 0,
  "retweets_count": 2,
  "likes_count": 3,
  "views_count": 133,
  "media_count": 0,
  "media_urls": [],
  "source": "http",
  "collected_at": "2026-10-14T12:57:41.624Z"
}
kind: "repost" (reposts dataset):
{
  "source_tweet_id": "2065225362544726371",
  "kind": "repost",
  "quote_tweet_id": null,
  "quoted_tweet_id": null,
  "url": "https://x.com/example_user",
  "created_at": null,
  "text": null,
  "screen_name": "example_user",
  "user_id": "1358024651956498433",
  "user_name": "Example User",
  "followers_count": 52,
  "following_count": 733,
  "replies_count": null,
  "retweets_count": null,
  "likes_count": null,
  "views_count": null,
  "media_count": 0,
  "media_urls": [],
  "source": "http",
  "collected_at": "2026-10-14T12:57:49.648Z"
}
Integrations & Automation
- Webhooks — act when a run finishes (e.g. push new quote tweets into a CRM or Slack).
- Zapier / Make — pipe engaged accounts into Google Sheets, Airtable or an outreach tool.
Recommended schedule: run hourly/daily for launch, PR or crisis monitoring (new quotes appear fast); weekly for competitive amplification reports.
FAQ
Does this use the official X / Twitter API?
No. It calls X's own GraphQL endpoints over plain HTTPS — the same ones the x.com website uses — so there is no API key, no official tier limits and no per-call API fee.
Why is a session cookie required?
Both quote tweets and the repost list are login-only on X. The actor reads auth_token / ct0 from secrets, so the session never appears in the input or the run record.
Do I need a browser or a residential proxy?
No. It runs as pure HTTPS requests (no Chrome, no Playwright) and does not need a proxy.
Why is coverage below 100%?
X hides quote tweets and reposts from deleted, suspended and protected accounts, and its search index (which backs the quotes tab) only exposes a slice of very large threads. Quote tweets typically land ~15–40% of the reported count; the repost list is a direct query and reached ~91% in the reference run. OUTPUT always reports the real coverage.
For AI Agents & LLM Apps
Purpose: return the quote tweets and/or the reposting accounts for one or more X posts as flat JSON records with author profile, engagement counts and media.
Minimal working input:
{ "tweetUrls": ["https://x.com/OpenAI/status/2065225362544726371"] }
Variant inputs:
{ "tweetUrls": ["2065225362544726371"], "collect": "reposts", "maxRepostsPerPost": 500 }
{ "tweetUrls": ["https://x.com/OpenAI/status/2065225362544726371"], "collect": "both" }
Output fields (both datasets, 24 columns): source_tweet_id, kind, quote_tweet_id, quoted_tweet_id, url, created_at, text, screen_name, user_id, user_name, avatar_url, bio, followers_count, following_count, verified, is_blue_verified, replies_count, retweets_count, likes_count, views_count, media_count, media_urls, source, collected_at. Run summary is in the key-value store item OUTPUT.
Behaviors an agent should know:
tweetUrlsis the only required field and accepts full URLs or bare numeric post IDs, including multiple posts per run.- There is no cookie field: the session must already exist as secrets
X_AUTH_TOKENandX_CT0, or the run will fail at the session step. collectchooses which dataset fills —quotes→ default dataset,reposts→ therepostsdataset alias,both→ both. Every row is taggedkind.0onmaxQuotesPerPost/maxRepostsPerPostmeans "until X stops serving new ones" — the default and the deepest collect; a non-zero value caps rows and nullscoverage_pct.- On repost rows, the post-specific columns (
created_at,text, engagement counts) arenullandurlis the retweeter's profile, not a post permalink.
Legal & Compliance Disclaimer
This actor is an independent tool and is not affiliated with, endorsed by, or sponsored by X Corp. It reads publicly visible post data plus login-only lists through your own X session (the auth_token / ct0 cookies you supply) — it is not a login bypass and holds no credentials of its own. It does not scrape data behind a login the user does not already hold, and does not solve CAPTCHAs. Use a throwaway account, and note X's Terms of Service and automation rules apply to your session. The output includes personal data (handles, display names, bios, avatars, follower counts); users are responsible for their own compliance with applicable data-protection law (including GDPR/CCPA where the data concerns EU or California individuals) and should not use it for unsolicited commercial outreach in violation of applicable law.
SEO Keywords
x quotes scraper, twitter retweeters scraper, quote tweet scraper, retweeter list, who retweeted my tweet, twitter engagement data, x api alternative, twitter quote tweets data, repost scraper, x retweeter data, twitter influencer discovery, x post amplification, quote tweet export, twitter sentiment analysis data, x scraper no browser, retweeter dataset, twitter lead generation, x quote tweets scraper, twitter competitor analysis, x engagement scraper, twitter scraper without api
FAQ
- Why is a session cookie required?
- Both quote tweets and the repost list are login-only on X. The actor reads auth_token / ct0 from secrets, so the session never appears in the input or the run record.
- Why is coverage below 100%?
- X hides quote tweets and reposts from deleted, suspended and protected accounts, and its search index (which backs the quotes tab) only exposes a slice of very large threads. Quote tweets typically land ~15–40% of the reported count; the repost list is a direct query and reached ~91% in the reference run. OUTPUT always reports the real coverage.
Input
Preview of the input form. Rent the Actor to fill it in and start runs from the console.
Fields
tweetUrlsOne or more X post URLs (https://x.com/user/status/123...) or numeric post IDs. Whatever the 'collect' mode selects is gathered for each post.
collectquotes = quote tweets only (default dataset). reposts = every account that reposted the post ('reposts' dataset). both = both lists, each in its own dataset. Every row is tagged kind='quote' or kind='repost'.
maxQuotesPerPostHow many quote tweets to collect per post. 0 = keep going until X stops serving new ones (the usual choice). Pagination depth is derived from this, so you never have to think in pages.
maxRepostsPerPostHow many accounts that reposted to collect per post. 0 = keep going until X stops serving new ones (the usual choice). Pagination depth is derived from this, so you never have to think in pages.
API
Bytewells speaks the Apify API. Existing integrations keep working: point apify-client at https://bytewells.com/api and use your Bytewells API token (Console → Settings → API access). The Actor ID is mercidev/x-quotes-reposts-scraper (or mercidev~x-quotes-reposts-scraper in URLs).
JavaScript · apify-client
import { ApifyClient } from 'apify-client';

const client = new ApifyClient({
  token: process.env.BYTEWELLS_TOKEN,
  baseUrl: 'https://bytewells.com/api',
});

const input = {
  "tweetUrls": [
    "https://x.com/OpenAI/status/2065225362544726371"
  ],
  "collect": "quotes",
  "maxQuotesPerPost": 10,
  "maxRepostsPerPost": 10
};

const run = await client.actor('mercidev/x-quotes-reposts-scraper').call(input);
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);
Python · apify-client
import os
from apify_client import ApifyClient

client = ApifyClient(os.environ["BYTEWELLS_TOKEN"], api_url="https://bytewells.com/api")

run_input = {
    "tweetUrls": [
        "https://x.com/OpenAI/status/2065225362544726371"
    ],
    "collect": "quotes",
    "maxQuotesPerPost": 10,
    "maxRepostsPerPost": 10
}

run = client.actor("mercidev/x-quotes-reposts-scraper").call(run_input=run_input)
items = client.dataset(run["defaultDatasetId"]).list_items().items
print(items)
HTTP · curl
curl -X POST "https://bytewells.com/api/v2/acts/mercidev~x-quotes-reposts-scraper/runs" \
  -H "Authorization: Bearer $BYTEWELLS_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"tweetUrls":["https://x.com/OpenAI/status/2065225362544726371"],"collect":"quotes","maxQuotesPerPost":10,"maxRepostsPerPost":10}'
Runs are billed as compute from your credit balance. Paid Actors need an active rental or trial; otherwise the API answers 402 rental-required.
Related
More Actors from the same publisher.
Pinterest Scraper | Pins | Search | Comments | Leads
Merci · @mercidev
The cheapest Pinterest scraper. Extract pins, search results, boards, and profiles with engagement stats, follower counts, comments, and HD image URLs.
MarketingSEO toolsSocial media$19/mo1-day free trial
Reddit Scraper | Posts | Comments | Subreddit Data
Merci · @mercidev
Scrape Reddit posts, comments, user profiles and subreddits by URL or keyword - full text, scores, authors and timestamps for sentiment, trend and research.
AutomationLead generationMarketing$20/mo1-day free trial
SoundCloud Scraper | Track Data & Direct Stream Links
Merci · @mercidev
Extract track and artist data from SoundCloud — titles, play counts, genres, stream links and engagement metrics for music analytics and discovery.
AIE-commerceLead generation$29/mo1-day free trial
Mobile.de Scraper | German Car Listings
Merci · @mercidev
Collect mobile.de vehicle listings across Germany. Get prices, mileage, first registration, power, fuel, gearbox, body type and other fields.
AIAutomationDeveloper tools$20/mo1-day free trial